Every digital system that claims fairness — from online lotteries and automated financial trading floors to cryptographic key generators and clinical trial randomization protocols — rests on a hidden, critical assumption: that its numbers are genuinely unpredictable. That assumption is rarely checked by the end users who depend on it for security or regulatory compliance. The mathematics of randomness exists to close this dangerous gap, replacing blind trust with measurable, verifiable evidence. A generator is not secure or random simply because its author or manufacturer says so; it is random because it survives an exhaustive battery of statistical and structural tests explicitly designed to detect bias and predictability.
Determinism Wearing a Random Mask
Software alone cannot produce true, absolute randomness. A pseudorandom number generator is fundamentally a deterministic algorithm: given the exact same initial seed, it will emit the exact same sequence of bytes forever. Its output only appears random to an observer who lacks visibility into the internal state or the seeding mechanism. This distinction matters enormously in real-world engineering. A generator incorrectly seeded with a current system timestamp, a process identifier, or a sequential session counter can be predicted months in advance by anyone who understands the seeding convention. Verification therefore splits into two separate, mandatory questions: is the generated sequence statistically well-behaved, and is the underlying internal state completely unknowable to an external adversary?
Entropy Is the Raw Material
True randomness must be harvested from physical, non-deterministic processes — thermal noise in semiconductors, timing jitter of high-frequency oscillators, atmospheric radio noise, or the microscopic chaos of hard disk head turbulence. Hardware entropy sources are conditioned, whitened, and mixed through cryptographic hash functions before use. The essential quality metric here is min-entropy rather than traditional Shannon entropy, because a determined attacker cares exclusively about the single most likely outcome, not the average behavior over time. A hardware source that produces a uniform distribution ninety-nine percent of the time but repeats a single value in the remaining one percent has far less usable entropy than its raw bitrate suggests, creating a vector for state compromise.
The Core Statistical Battery
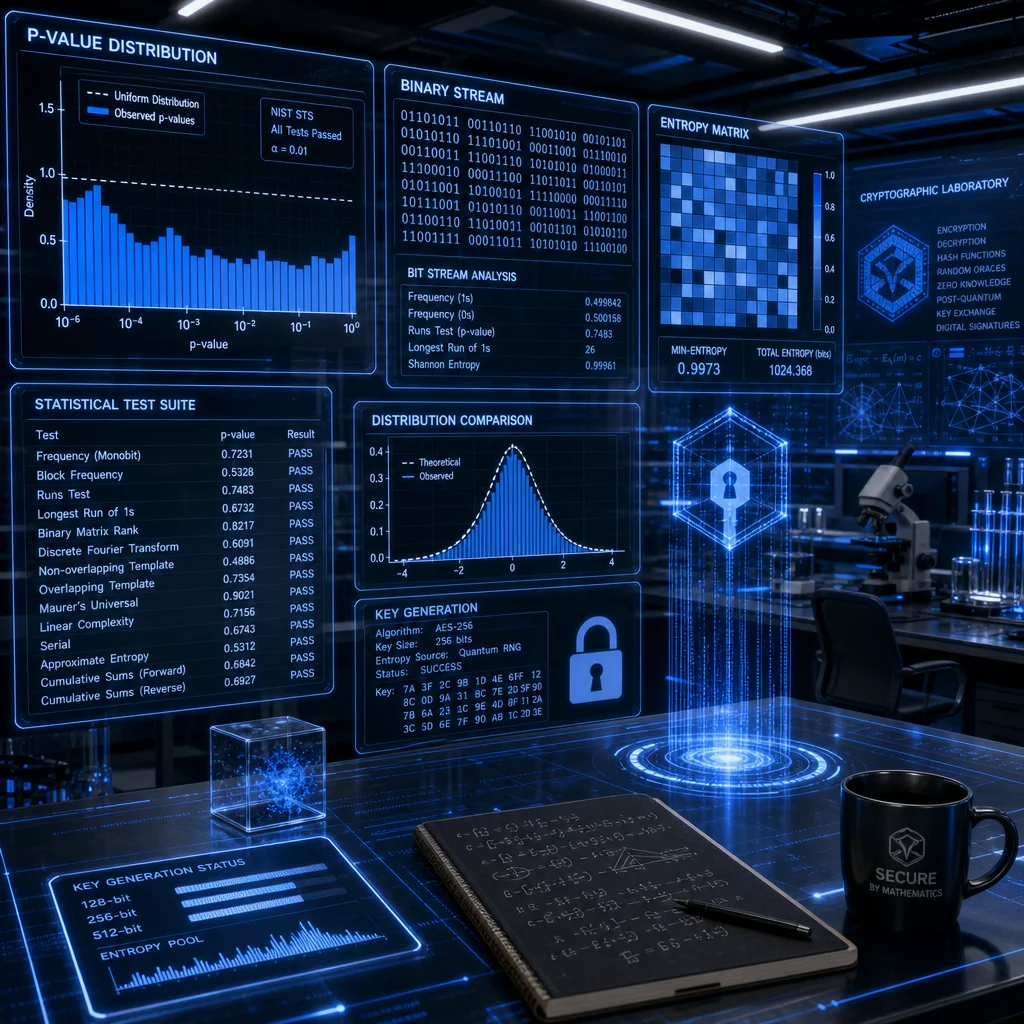
Classical verification begins with fundamental evaluations like the monobit frequency test, which evaluates whether zeros and ones appear in roughly equal numbers across the dataset. The block frequency test repeats that inquiry across smaller segments, catching slow behavioral drifts that global counts hide. The runs test examines how often identical bits cluster together, since excessive clustering or excessive alternation both indicate underlying structural flaws. The longest-run-of-ones test targets the extreme tails of clustering, where hardware weaknesses usually appear first. Each of these tests returns a probability distribution rather than a simplistic yes-or-no answer, and misunderstanding this nuance is where most misguided security audits fail.
Beyond these fundamentals, rigorous practitioners deploy matrix rank tests to check for linear dependence, discrete Fourier transform tests to uncover periodic components, serial and approximate entropy tests to flag higher-order correlations, cumulative sums tests for directional drift, and template matching tests that search for short patterns appearing more often than random chance allows. A generator can easily pass the first six metrics and still collapse entirely under template matching — which is precisely why no serious cryptographic audit relies on a single isolated statistic.
From p-Values to Verdicts
Statistical testing never mathematically proves randomness; it only fails to disprove the hypothesis of randomness. Every individual test yields a p-value, and a healthy, unbiased generator should produce p-values that are themselves uniformly distributed between zero and one. This is the deeply counterintuitive heart of the discipline: you do not evaluate a single p-value in isolation; you evaluate thousands of them collected across multiple iterations. A two-level testing procedure applies a chi-square goodness-of-fit test to the entire collection of p-values, flagging a generator when too many results pile up suspiciously near zero or near one. Anyone who runs a single test, sees 0.41, and declares success has measured almost nothing.
Structural Tests the Eye Cannot See
Standard statistical suites catch frequency anomalies but often miss geometric ones. The spectral test examines lattice structures inherent in linear congruential generators, where consecutive outputs fall onto distinct hyperplanes in high-dimensional space. Serial correlation analysis reveals lagged relationships completely invisible in aggregate counts. Birthday spacings tests, compression tests, and gap tests target subtle regularities that survive conventional screening. A scatter plot of adjacent pairs is often the fastest diagnostic tool of all: a well-behaved generator fills the Cartesian plane evenly, while a flawed one reveals distinct stripes, bands, or geometric patterns.
Seeds, States, and the Predictability Trap
Even the strongest cryptographic generator becomes instantly worthless if paired with weak seeding practices. Seeds must be drawn exclusively from a high-entropy hardware source at every system initialization, never derived from predictable values such as boot times, network interface MAC addresses, or incremental counters. The internal state must be large enough in bits to resist brute-force reconstruction and must be reseeded periodically to bound the potential window of damage from any single state compromise. Forward secrecy matters profoundly: recovering past outputs from the current internal state should be computationally infeasible, and compromising the active state must not reveal prior historical values.
Adversarial Thinking: Testing Like an Attacker
Statistical verification answers whether output looks random to a mathematical formula. Security verification answers whether a resourceful attacker can predict it. These are fundamentally different questions requiring entirely different tooling. Adversarial review reconstructs the source algorithm, attempts internal state recovery from observed outputs, probes for timing side channels in the entropy collection pipeline, and checks whether system shutdown conditions cause a fallback to an insecure deterministic path. Many historical software failures were not statistical at all — the numbers looked pristine while the underlying seed space was small enough to enumerate via brute force in a matter of minutes.
Reproducibility and the Audit Trail
Real integrity claims must be independently verifiable by third-party outsiders. A credible audit log records the exact generator version, the test suite version, the number of samples analyzed, the master seed used for the test harness itself, and the full numerical distribution of generated p-values. Any auditor should be able to rerun the identical verification procedure and obtain the identical cryptographic verdict. Without this strict discipline, verification becomes mere theater: a compliance report that simply says passed, with no traceable path back to the raw empirical evidence that produced it.
A Practical Verification Pipeline
A workable verification pipeline operates in distinct stages. First, document the hardware entropy source and measure its min-entropy under both normal operating conditions and simulated degraded states. Second, subject the conditioned output stream to at least fifteen complementary statistical test suites on samples of one million bits or more, repeating across multiple independent initialization seeds. Third, analyze the resulting p-value distribution rather than individual outcomes. Fourth, conduct adversarial penetration testing against the seeding and state management logic. Fifth, log every parameter and schedule periodic re-verification, as hardware ages, firmware updates, and entropy sources can degrade silently over time.
Conclusion: Integrity Is a Process
Randomness cannot be certified once and simply forgotten. Entropy sources drift, implementations get refactored, and assumptions rot quietly between software releases. Probabilistic integrity is therefore not a static property a system possesses, but an active discipline a team practices: measuring min-entropy, running complementary test batteries, examining p-value distributions, aggressively attacking your own seeding logic, and documenting enough data that a stranger could repeat every step. The mathematics of randomness offers no final certificate of immunity — only a continuous, honest conversation with uncertainty, conducted with rigorous numbers instead of comforting assurances.
“