Why Compliance Is a Moving Target
Regulations evolve significantly faster than standard product release cycles. A compliance rule that shaped your architecture twelve months ago might be entirely obsolete this quarter. New geographic markets introduce strict data localization requirements, new third-party vendors expand your risk surface, and newly shipped features constantly interact with sensitive categories of user data. When platforms treat compliance as a periodic, one-time project, they inevitably drift out of alignment. Most organizations only discover these invisible gaps when an external auditor or an enterprise client requests proof during a critical deal review.
The pragmatic solution is an institutionalized compliance protocol. A robust protocol establishes a repeatable methodology for determining what guarantees the platform must uphold, assigning absolute accountability to specific team members, and continuously testing those guarantees. This transforms compliance from an agonizing annual fire drill into routine engineering work that ships safely alongside your core product features.
The Four Layers of a Working Protocol
High-performing, mature engineering platforms consistently converge on a four-layer compliance framework. While implementation details vary across tech stacks, the underlying structural pattern remains identical:
- Policy: Documented, unambiguous rules translating legal statutes and master service agreements into engineering requirements. Every rule must have a designated owner, a defined technical scope, and an explicit definition of what constitutes a passing state.
- Control: The active mechanism that enforces or verifies the adherence to a policy. Controls can be technical (such as automated infrastructure access logging or encryption enforcement) or procedural (such as quarterly privilege reviews).
- Evidence: The immutable artifact generated when a control executes successfully. Raw audit logs, CI/CD security reports, cryptographically signed deployment approvals, and vulnerability scan tickets all serve as valid evidence.
- Review: A scheduled human verification cycle confirming that controls remain fully functional and that generated evidence accurately reflects system reality.
A control lacking verifiable evidence is merely an empty promise. Evidence gathered without periodic review transforms into an unorganized graveyard of files. Real value emerges exclusively when all four layers interconnect, allowing engineers and auditors to trace any legal requirement directly down to a specific line of code or a cloud resource configuration.
Designing the Technical Audit
A technical audit is fundamentally different from a standard penetration test. It answers a much more targeted question: does the underlying system architecture behave precisely as our compliance policies mandate? To answer this definitively, break the audit down into five distinct, actionable checks:
First, execution of a comprehensive infrastructure inventory. You cannot secure or audit assets you cannot see. Every microservice, managed database, message queue, object storage bucket, and SaaS integration requires an active record with a named engineering owner. Unmapped shadow assets remain the single most common finding during initial technical audits.
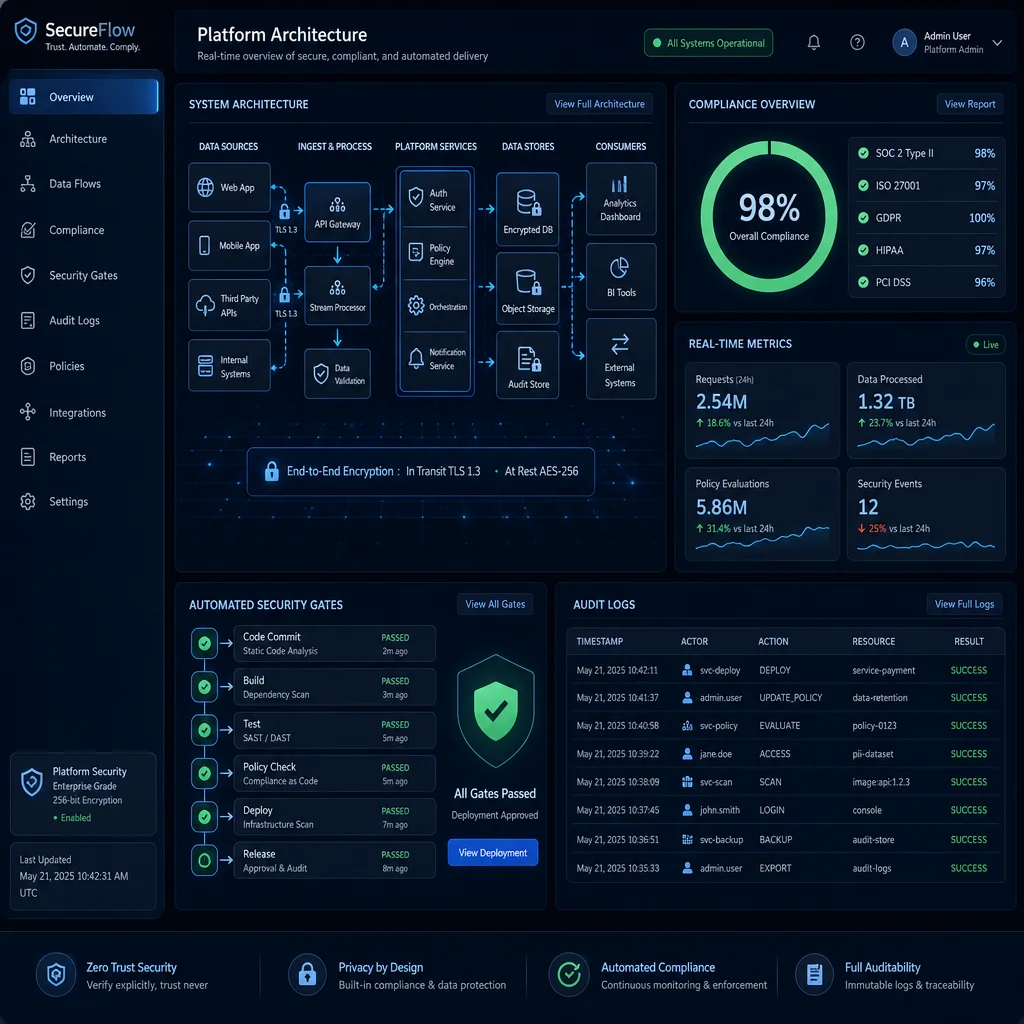
Second, rigorous data flow mapping. Trace exactly where sensitive user data is ingested, copied, cached, exported, transformed, and ultimately purged. Pay acute attention to backup systems, internal analytics pipelines, and customer support tooling. These secondary systems frequently contradict the official data flow diagrams.
Third, thorough access control audits. Review precisely who and what can read, write, or delete production data, including third-party service accounts, developer access keys, and CI/CD deployment tokens. Actively hunt for stale administrative permissions, hardcoded shared secrets, and long-lived tokens that have outlived their original engineering purpose.
Fourth, configuration baseline validation. Programmatically compare running cloud infrastructure against your approved baseline specifications. Cryptographic settings, perimeter security rules, loggingverbosity, and data retention windows represent the primary points of configuration drift.
Fifth, forensic change history analysis. Audit recent production deployments, emergency hotfixes, and manual infrastructure interventions. If any change bypassed standard peer review or automated deployment gates, the audit must document why it occurred and what newly implemented safeguard prevents future recurrence.
Always scope your technical audit around an end-to-end business process rather than an isolated organizational chart. For instance, following a single automated customer refund request through your system touches customer support platforms, payment gateways, microservices, data warehouses, and financial export routines. That single functional journey exposes operational and compliance realities that three separate departmental reviews would completely miss.
Making Audits Repeatable and Predictable
A single audit generates a static report. A true compliance protocol establishes a predictable rhythm. Align your audit cadence directly with operational risk: high-impact core payment systems require quarterly reviews, medium-impact supporting services demand semi-annual evaluations, and low-risk environments can be audited annually. Maintain strict scope consistency between cycles to accurately compare metrics and identify emerging architectural trends.
Automate everything that can be reliably automated. Automated configuration drift detection, IAM permission diffs, software bill of materials (SBOM) checks, and log retention verification should all execute as scheduled CI/CD jobs. Crucially, automate data collection rather than human judgment. A trained engineer must still review raw outputs to evaluate whether a specific finding poses genuine operational risk.
Store audit findings in the exact same issue tracker your engineering teams use daily for product development. Compliance requirements buried in isolated spreadsheets are inevitably forgotten during intense product release cycles. When a compliance finding lives alongside feature backlog items, it receives proper sizing, prioritization, and timely remediation.
Treat automation failures as compliance findings in their own right. A scheduled compliance scan that silently failed three months ago creates dangerous false confidence and is far worse than having no scan at all. Implement strict heartbeat monitoring for every automated compliance control.
Roles and Accountability
A compliance protocol breaks down silently when every team member assumes someone else is watching the metrics. Explicitly assign three core compliance roles. The requirement owner defines policy intent and signs off on structural changes. The control owner designs, builds, and maintains the technical enforcement mechanism. The independent auditor verifies execution quality and reports directly to executive leadership without filtering. In lean engineering teams, a single senior engineer may hold multiple roles, but the structural separation must be clearly defined on paper and respected in everyday practice.
Incorporate these accountability roles directly into developer onboarding materials. New engineers should learn during their first week which platform components are in regulatory scope, which data fields are classified as sensitive, and who specifically to contact when a proposed architectural change might impact either.
Evidence That Survives Rigorous Scrutiny
Compliance evidence is only valuable if an external, independent third party can understand and verify it months later. Every collected artifact must answer four foundational questions: precisely what was tested, exactly when did the test run, who or what executed it, and what was the definitive numerical or binary result. Exact timestamps and exact software version references are mandatory. A screenshot of an administrative dashboard without a generation date or system context is completely worthless.
Always favor raw, machine-generated evidence over human-written summary memos. An unedited, timestamped API export from your enterprise identity provider is significantly harder to dispute than a carefully crafted executive document, and it requires vastly less engineering overhead to produce.
Retain compliance evidence strictly for the retention period mandated by your most stringent regulatory obligation. Immediately purge the data once that window closes. Holding sensitive logs or user data longer than legally required introduces unnecessary liability, and modern auditors scrutinize data deletion policies just as closely as data ingestion protocols.
Vendors and the Extended Software Surface
No modern software platform operates in total isolation. Cloud infrastructure providers, error tracking tools, transactional email gateways, payment processors, and customer analytics platforms all reside squarely inside your compliance boundary whether acknowledged or not. Maintain an exhaustive, up-to-date vendor register detailing the exact categories of data each partner receives, the governing contract terms, and scheduled review dates for their SOC 2 or ISO documentation.
Before onboarding any new SaaS tool, rigorously question what data the integration genuinely requires. Most modern software integrations request dangerously broad administrative access by default. Enforce the principle of least privilege at setup, and programmatically verify that the restricted access scope holds over time. Re-evaluate vendor security postures annually, or immediately following any disclosed security incident.
Common Failure Modes
Certain systemic anti-patterns appear repeatedly across software organizations of every scale:
- Drafting complex compliance policies written exclusively for lawyers rather than engineers, rendering them impossible to practically implement.
- Relying on theoretical controls that exist solely in documentation and were never actually coded or deployed.
- Quietly shrinking the technical audit scope year-over-year to bypass uncomfortable infrastructure findings.
- Accumulating massive repositories of unreviewed evidence, allowing broken controls to remain undetected indefinitely.
- Failing to assign a named owner to a specific requirement, ensuring nobody notices when the control inevitably fails.
Every single one of these failure modes is completely fixable. The essential first step is documenting them honestly within your internal audit reports rather than softening the language to appease stakeholders.
Metrics Worth Tracking
You cannot effectively manage platform compliance using a single monolithic score, but a tightly focused set of indicators keeps engineering attention properly aligned. Track the exact percentage of compliance requirements with an assigned owner. Measure finding closure velocity categorized by severity. Monitor the total count of unmapped shadow assets. Track the ratio of automated controls versus manual checklists. Measure the frequency of production deployments that bypass standard review gates.
Review these operational metrics during the exact same engineering meetings where you analyze service uptime, latency percentiles, and incident post-mortems. This strategic placement signals clearly that compliance is a core component of software engineering quality, rather than an isolated administrative ritual.
Set finding remediation targets that are realistic for your current engineering headcount. An overly aggressive closure target that nobody can realistically hit teaches engineers to close compliance tickets without actually fixing underlying technical debt, which is far more dangerous than maintaining an honest, transparent backlog.
Culture Is the Ultimate Control
Robust protocols and automated technical audits catch a vast number of issues, but psychologically safe engineering teams catch even more. Developers who feel secure reporting an accidental misconfiguration will flag infrastructure drift long before it triggers a security incident. Engineering cultures that treat audit findings as valuable learning opportunities will systematically eliminate root causes, while punitive cultures merely teach developers to hide the next vulnerability.
Keep your compliance processes straightforward, your terminology plain, and your engineering feedback loops exceptionally tight. A compliance protocol that a backend engineer can read in ten minutes and seamlessly apply in their next pull request will consistently outperform a hundred-page PDF that nobody ever opens.
A Practical Starting Point
If your platform has never operated under a formal compliance protocol, start remarkably small. Select one critical data flow—such as user account creation or payment tokenization. Fully map that single path, assign one absolute owner, define one concrete technical control, and run a single test audit. Collect the verifiable evidence, review the results together within thirty days, and then repeat the exact same pattern for the next data flow. Six steady months of iterative execution will easily outperform an entire year of paralyzing theoretical planning.
Compliance is never a static destination you finally reach. It is a disciplined engineering habit you maintain, verified one honest technical audit at a time.
“