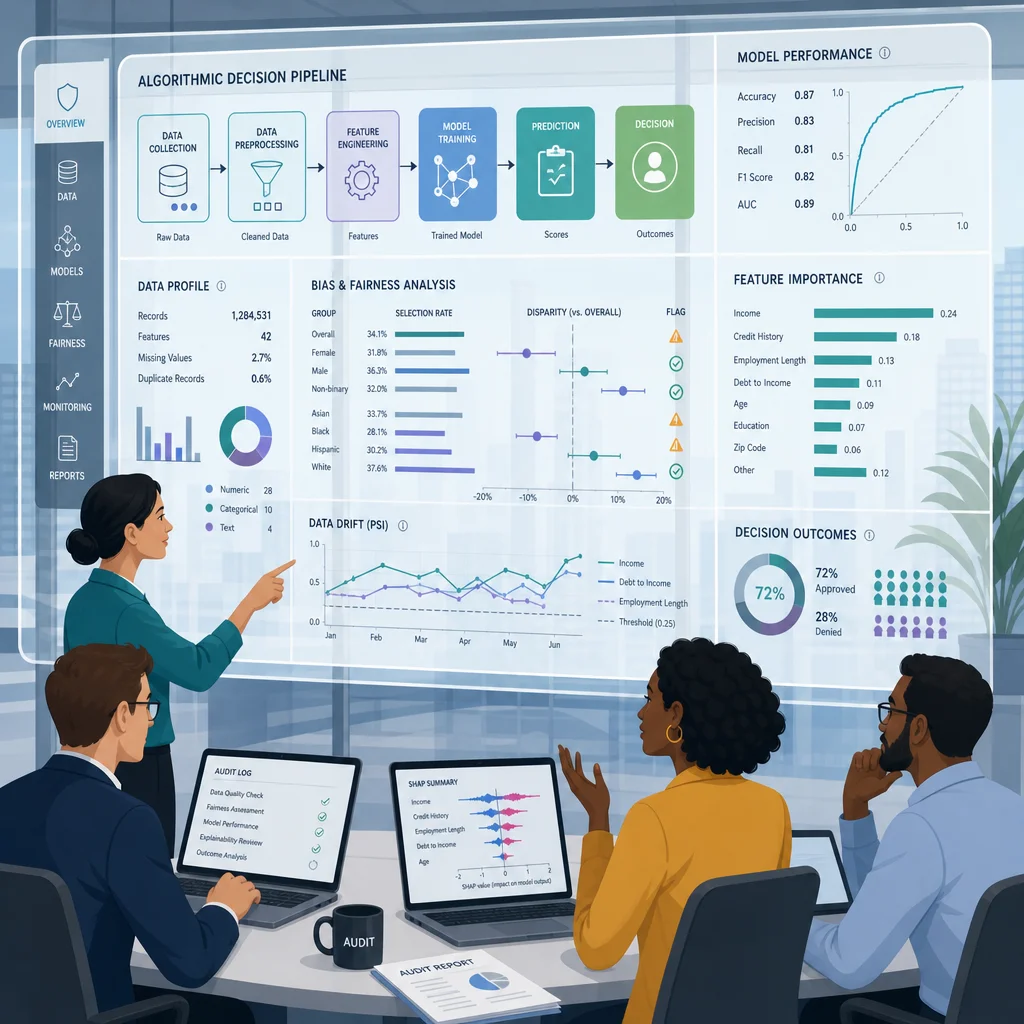
Governments increasingly rely on automated algorithms to allocate critical public resources: determining housing benefits, assigning school places, dispatching emergency response units, and selecting tax returns for comprehensive audits. These high-stakes computational choices directly shape human lives, economic stability, and civil rights. When a public administration cannot clearly articulate how a machine learning model or automated rule engine reached a specific verdict, public trust collapses. Consequently, the debate has shifted from whether algorithms belong in public governance to how independent external actors can systematically evaluate them. This article outlines the principal methodologies for assessing algorithm transparency in public decision-making, moving beyond superficial compliance to rigorous technical, institutional, and participatory audits.
Defining the Dimensions of Transparency in Public Systems
Transparency is not a monolithic metric. An effective evaluation framework must first isolate which layer of the socio-technical stack is under review. In practice, five distinct layers demand rigorous scrutiny:
- Disclosure of existence: Formally notifying the public that an automated system actively participates in decision-making processes.
- Disclosure of data: Documenting the exact inputs, training datasets, sampling methodologies, and known data biases.
- Disclosure of logic: Translating underlying mathematical rules, feature weights, or optimization objectives into accessible, human-readable terms.
- Disclosure of performance: Publishing empirical accuracy metrics, false positive and negative error rates, disparate impact analyses, and known failure modes across demographic groups.
- Disclosure of redress: Establishing clear, accessible pathways for individuals to challenge an automated decision and secure a mandatory human review.
Any evaluation study that audits only a single layer—such as checking whether a model card exists—and labels the entire system “transparent” is fundamentally misleading.
Method One: Comprehensive Documentation Audits
Documentation audits serve as the baseline and most cost-effective starting point for evaluators. The assessment team collects all available artifacts provided by the public agency: model cards, technical data sheets, algorithmic impact assessments, procurement contracts, validation test reports, and internal standard operating procedures. Each document is scored against a rigorous, predefined rubric. Does the paperwork explicitly name the model owner? Does it state the intended operational context and known environmental limits? Does it record the specific timeframe of the training data?
To ensure methodological rigor, two independent reviewers should code the same documentation set separately. A disagreement rate exceeding twenty percent indicates that the evaluation rubric is ambiguous and requires immediate refinement. However, the inherent limitation of documentation audits is that they measure what an agency claims about its systems rather than operational reality. A polished model card can easily mask an unvalidated, biased system. Consequently, documentation audits should be treated as a preliminary filter to determine where intensive technical testing is required.
Method Two: Transparency Indices and Disclosure Scoring
Academic researchers and civil society organizations frequently construct composite indices to rank public bodies by their disclosure practices. Evaluators establish a weighted set of indicators, publish the evaluation rubric transparently, and apply it to a representative sample of administrative agencies. Because overall rankings are highly sensitive to weighting choices, the rationale behind each weight must be justified in advance. A reliable approach involves scoring individual indicators on a zero-to-three scale and publishing both aggregated totals and disaggregated sub-scores, allowing external readers to re-weight metrics based on their own priorities.
While composite indices excel at generating institutional pressure and highlighting regulatory outliers, they rarely explain the underlying institutional reasons for poor performance. They should always be paired with qualitative case studies to contextualize the scores.
Method Three: Black-Box Testing with Counterfactuals
Black-box testing focuses strictly on behavioral observation rather than internal system claims. Evaluators submit synthetic, non-sensitive test cases that vary by a single isolated attribute—such as a specific postal code, demographic indicator, or historical marker—and systematically compare the resulting outputs. A disproportionately large shift in the administrative outcome driven by a trivial change in input exposes hidden proxies or dangerous algorithmic sensitivities. Repeatedly probing the system also reveals its output stability.
This approach requires zero access to proprietary source code, making it highly accessible to investigative journalists, regulatory watchdogs, and civic technology groups. Nevertheless, strict ethical boundaries are mandatory: never input real, personally identifiable citizen data, and avoid probe frequencies that could degrade or disrupt live public services. Evaluators should always request a designated sandbox or staging environment from the agency prior to testing.
Method Four: Participatory and Deliberative Evaluation
Affected communities frequently identify real-world harms that purely mathematical audits overlook. Participatory evaluation methodologies integrate impacted residents, frontline caseworkers, and advocacy groups directly into the assessment workflow. A standard framework utilizes structured community workshops where participants examine system descriptions, catalog grievances, and score the severity of identified risks through modified Delphi methods or citizens’ panels.
The resulting output is a weighted harm register grounded in lived experience rather than abstract statistical averages. While deliberation requires significant time, administrative resources, and skilled facilitation, it imparts a degree of democratic legitimacy that technical audits cannot achieve on their own.
Method Five: Process Tracing and Institutional Mapping
Many transparency failures originate in organizational silos rather than flawed code. Process tracing follows an administrative decision from initial data ingestion through to the final notification letter, meticulously logging every human and automated handoff. Who originally authorized the model? Who configured the decision threshold? Who signs off on adverse outcomes? Mapping these operational handoffs exposes systemic vulnerabilities, such as unassigned sign-off responsibilities, ambiguous departmental ownership, or vendor contracts with non-disclosure clauses that block public oversight.
By combining freedom-of-information requests, internal administrative manuals, and staff interviews, evaluators build a precise institutional flowchart with a named human owner at every single node. If a decision node lacks a clear owner, public accountability has broken down.
Method Six: Reproducibility and Replication Studies
Reproducibility stands as the ultimate benchmark of authentic algorithmic disclosure. The evaluator requests sufficient technical detail to independently rebuild the model scoring pipeline or rerun the evaluation metrics on an isolated validation dataset. While full replication of proprietary models is exceptionally rare, partial replication provides immense diagnostic value. Can an independent outside team recreate published error rates using the documented data pipeline? If not, precisely which operational step remains undocumented? Publishing a replication report—even a failed one—provides the public with a definitive boundary where transparency ceases.
Method Seven: Longitudinal Monitoring and Incident Reporting
Transparency is never a static, one-time compliance report. Algorithms suffer from performance drift as socio-economic conditions evolve. A robust monitoring framework tracks error rates, appeal volumes, and complaint categories across rolling timeframes. Incident reporting mechanisms allow frontline workers to log unexpected algorithmic behavior, feeding a public incident register that closes the feedback loop. Regular review cycles with publicly accessible meeting minutes far outperform passive annual reports that escape public scrutiny.
Method Eight: Adversarial Review and Red Teaming
Red teaming deploys a specialized adversarial group tasked with breaking the operational assumptions of an algorithm. The team intentionally engineers extreme inputs designed to trigger inconsistent, biased, or absurd administrative outputs. In the public sector, red teams must include domain experts—such as social welfare case managers or school admissions officers—who understand real-world edge cases. Discoveries are logged in a shared risk register with severity classifications. This methodology is rapid, cost-effective, and exposes systemic flaws that standard statistical testing routinely misses.
Designing Indicators Resistant to Strategic Gaming
Any evaluative metric that becomes an administrative target will inevitably be gamed. If an index rewards the mere publication of a model card, agencies will publish minimal, superficial documents. Robust indicators therefore couple a formal presence check with an active quality verification. For instance, rather than asking simply whether an impact assessment exists, evaluators must verify whether it identifies specific affected groups, publishes true error rates, and details actionable mitigation strategies. Whenever feasible, independent verification and randomized sampling should replace unverified agency self-reporting.
Synthesizing Methods into a Unified Evaluation Framework
No single methodology provides a complete assessment. A resilient evaluation framework operates across four sequential stages:
- Baseline audit: Conducting documentation reviews and institutional mapping to establish system parameters.
- Technical probing: Executing black-box counterfactual tests and red teaming on high-risk decision nodes.
- Democratic review: Engaging affected communities through participatory panels and harm registers.
- Continuous oversight: Implementing longitudinal monitoring and public incident reporting.
Each stage concludes with a concise public brief detailing what was tested, what was discovered, and what remains unknown. Acknowledging operational blind spots is a core indicator of evaluation integrity.
Legal and Ethical Guardrails for Evaluators
Because these evaluation methodologies interact with sensitive personal data and public institutions, strict ethical guardrails are paramount. Independent evaluators must secure formal ethics board approval prior to testing with human subjects, utilize synthetic or thoroughly anonymized datasets, and negotiate clear disclosure agreements that ensure findings are published rather than suppressed. Agencies should be granted a brief right of reply, but never a veto over independent findings. Whistleblowers and frontline personnel reporting system failures must be legally protected. Finally, evaluators must fully disclose their funding sources and any prior consulting relationships to maintain unimpeachable independence.
Core Pitfalls to Avoid
Evaluators must navigate several recurring mistakes. Measuring transparency purely by counting published pages rewards administrative volume over substantive clarity. Relying exclusively on vendor assurances introduces severe conflicts of interest. Equating local explainability of a single decision with systemic public accountability confuses micro-level interpretation with macro-governance. Ignoring the redress layer leaves citizens defenseless. Most importantly, conducting evaluations without a mandated follow-up mechanism reduces vital oversight to a report left gathering dust on a shelf.
Practical Checklist for Transparency Evaluation
- Explicitly define the target transparency layer prior to data collection.
- Publish the evaluation rubric, indicators, and weightings in advance.
- Utilize two independent coders for any qualitative document review.
- Restrict testing strictly to synthetic cases and secure written permissions for sandboxes.
- Integrate affected communities directly into the risk prioritization workflow.
- Assign a named human owner to every single node in the decision chain.
- Explicitly document aspects of the algorithm that could not be verified.
- Establish mandatory review milestones and publish meeting minutes openly.
Conclusion
Evaluating algorithm transparency in public decision-making is a rigorous professional craft, not a simple compliance checklist. Documentation audits, disclosure indices, black-box counterfactual tests, participatory panels, process tracing, and longitudinal monitoring each answer fundamentally different questions. Deployed in tandem, they provide regulators, journalists, and citizens with an accurate, unvarnished picture of automated governance, establishing clear institutional accountability and highlighting persistent blind spots. The most credible evaluations are invariably those that transparently state what they were unable to see.